/ About this event
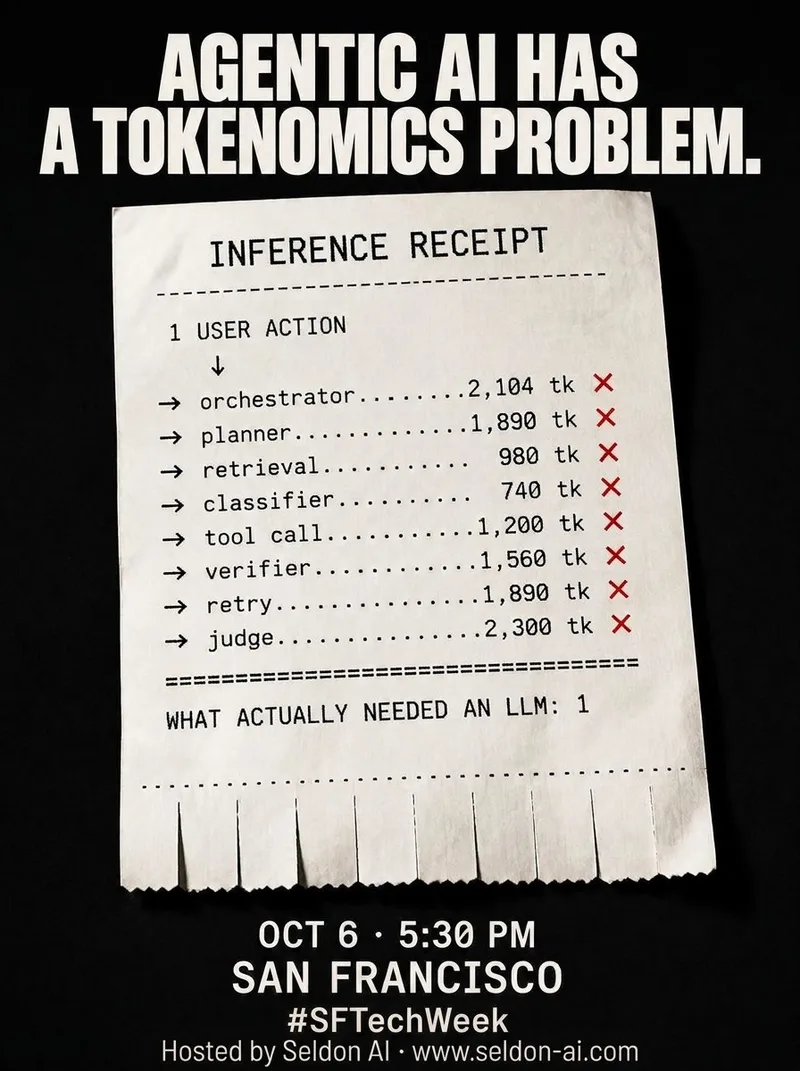
AI applications are consuming more models, more tokens and more compute than ever. Agents make the problem even bigger: a single user action can trigger dozens—or hundreds—of model calls.
But how many of those calls actually require an LLM?
Join AI infrastructure founders, engineers and technical leaders for a practical discussion on the next phase of production AI: inference economics, model routing, deterministic execution, evals and what happens when repeated AI workflows can be turned back into software.
We’ll tear down real-world AI workflows and ask:
Which tasks genuinely require model intelligence? Which can move to smaller models, rules or deterministic pipelines? How should teams trade off cost, latency, reliability and quality? What does the production AI stack look like as agents scale token consumption? And when should an LLM call stop being an LLM call at all?
Expect technical perspectives, real workflow teardowns and an open discussion with people building and operating production AI systems.
For: CTOs, AI/ML engineers, infrastructure teams, technical founders and anyone operating meaningful production LLM workloads.
Hosted by Seldon AI (www.seldon-ai.com) during SF Tech Week.
This event is a part of #SFTechWeek—a week of events hosted by VCs and startups to bring together the tech ecosystem. Learn more at www.tech-week.com.


