/ About this event
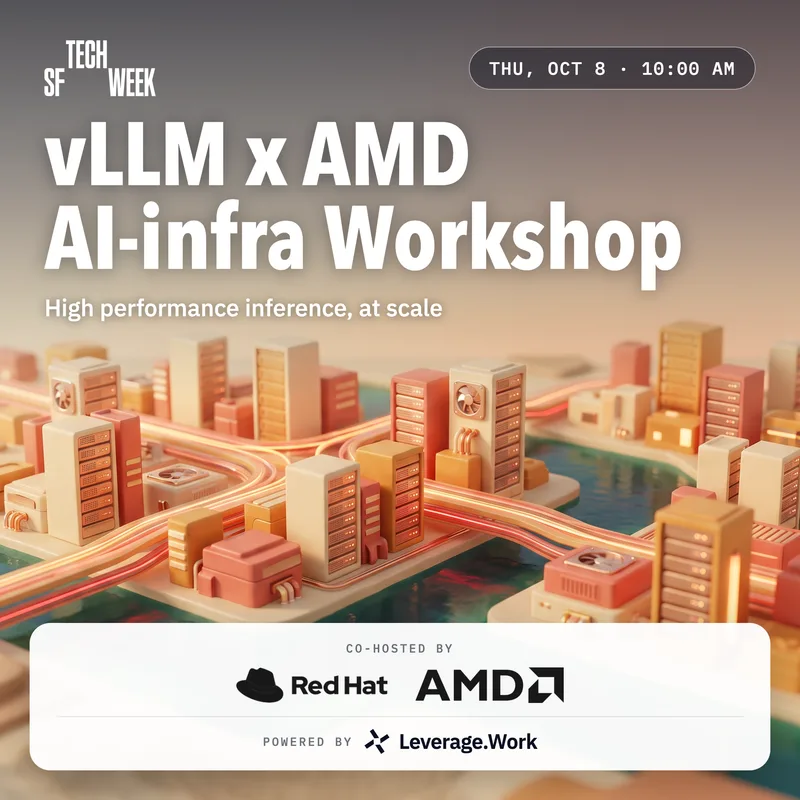
Join AMD, Cerebras, MoonMath AI, Red Hat, and the vLLM project for an in-person half day on open source inference, ending with a hands-on workshop you can follow along with on your own laptop.
Self-hosting open models is now a real option for teams that want high performance without per-token costs. We will cover how vLLM and llm-d make distributed inference fast at scale, and how being smarter about which model serves which request cuts your inference bill without giving up quality.
This event is first come, first serve and attendance will be capped at 100 participants.


