/ About this event
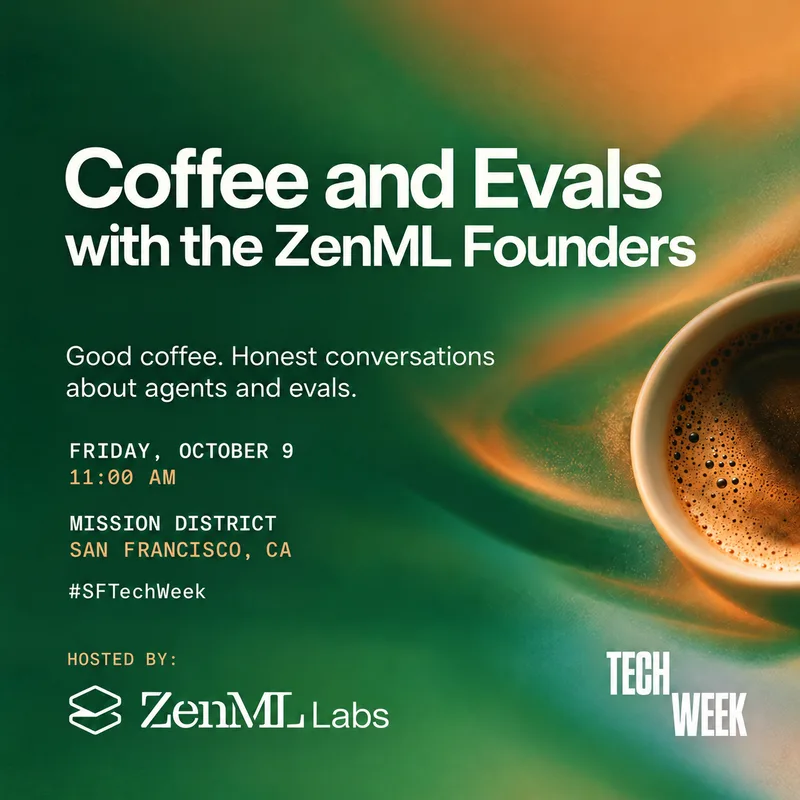
Grab a coffee with Hamza Tahir and Adam Probst, co-founders of ZenML Labs. We want to hear how you're evaluating your models and agents: what's working, what's breaking, and what you've stopped trusting.
ZenML is the open-source, unified infrastructure layer for running AI in production. Kitaru, built by the same team, is open-source, replay-based evals for agents. You import your production traces, turn what your team notices into evaluators, and replay real sessions against your next model or prompt change before it ships.
We're now building Kaizen, an autonomous AI engineer that runs your agents, writes your evals, and trains your models. It works in the background, watching your production agent traces and spotting where things fall short. From there it acts. It turns failures into better evals, with you in the loop, and fine-tunes open-weight models for your specific tasks.
Our vision is continuous improvement as the default. Today, getting from "this agent failed in production" to "this agent is now better" takes weeks of manual work: digging through traces, writing test cases, curating data, and running training jobs. Kaizen closes that loop on its own, so your agents get better every day instead of every quarter.
Evals are the hardest part to get right, and that's what we want to talk about. There are no slides and no pitch deck, just a small group of practitioners comparing notes over good coffee.


